How does RankX measure AI search readiness?
We score your site across nine published, weighted areas. Every finding shows its evidence, and anything we didn’t measure is marked “Not assessed”.
How can I check your work?
Now
Evidence under every finding
Each finding links to the crawl, check or rule behind it.
Now
“Not assessed”
A check that didn’t run gets no score.
Now
Confidence marks
“Heuristic” means a rule of thumb, not a direct measurement. “To verify” means the judge model was uncertain and flagged it for a person to check.
Now
Set aside on review
An analyst can set a finding aside but must give a reason. It leaves the action plan and appears under “Set aside on review”.
Coming
Recorded human overrides
Every override logged, building an evaluation set over time.
Coming
Change over time
Today, change is measured by re-auditing fixes.
How is the score calculated?
Nine areas, each out of 100, combined as a weighted mean. Each report prints the method version used in its appendix.
| Area | What it covers | Weight |
|---|---|---|
| Content quality | Do pages answer questions clearly | 17.4% |
| Crawl and indexing | Can crawlers reach and index the site | 17.4% |
| On-page | Titles, headings, page signals | 13.0% |
| Search visibility and authority | Market and authority data | 13.0% |
| AI search readiness | AI crawler access, editorial heuristics | 10.4% |
| Links and architecture | Internal links, site structure | 8.7% |
| Performance | Page speed (needs the performance module) | 8.7% |
| Structured data and sharing | JSON-LD, sharing metadata | 7.0% |
| Security and trust | HTTPS, baseline trust | 4.3% |
Not assessed. If a check didn’t run, that area isn’t scored, and the overall score uses only assessed areas.
Hard caps.
- Blocked from search: capped at 20 overall.
- Not reliably on HTTPS: capped at 60 overall.
- Search footprint under 10 keywords and 10 in estimated traffic: Search visibility capped at up to 30.
Model judgment. Only Content quality and AI search readiness use it, at 70% weight when usable page judgments exist. AI search readiness uses editorial heuristics because Google says there are no additional requirements, and no special optimizations needed, to appear in AI Overviews or AI Mode, beyond its usual SEO best practices (Google Search Central, checked 17 October 2026).
The score is a summary. The findings are what matter.
What does the audit measure, and what doesn’t it?
This split is printed on every report cover.
| What | Status |
|---|---|
| Site crawl and page checks | Measured |
| AI crawler access (robots.txt) | Measured |
| Page speed | When in scope; otherwise Not assessed |
| Mentions and citations in ChatGPT, Gemini, Claude, Perplexity | Coming |
| Change in mentions and citations over time | Coming |
| Positions inside AI answers | Not measured: answers vary run to run |
| Revenue or leads caused by AI search | Not measured: we don’t forecast revenue or leads |
Data sources. Our own crawl, plus third-party search and AI-answer data.
When does a fix count as verified?
Only when we re-run the same check under the same inputs after the fix. Each fix is reported as verified fixed, still open, or not rechecked.
What happens when the method changes?
The version changes, and every report cites the version it used. Earlier versions are available on request.
Last updated 17 October 2026
Coming
How will prompt measurement work?
It isn’t sold yet, and reports mark it “Not measured”. Here’s the plan, so you can judge it in advance.
- Tools: ChatGPT, Gemini, Claude, Perplexity and Google AI Overviews. Claude is checked through its API with web search, not the Claude app, and reported separately. Any change is a new method version.
- Panel: drafted for your industry and area, agreed with you, versioned.
- Runs: same prompts, tools and logged-out conditions, each stamped with tool and date.
- Variance: reported, with logged answers kept. One odd answer isn’t a trend.
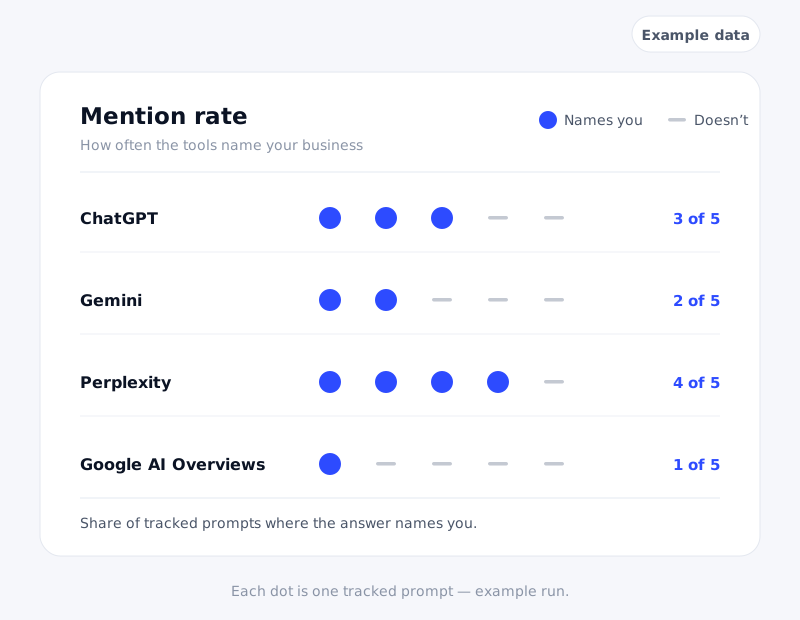
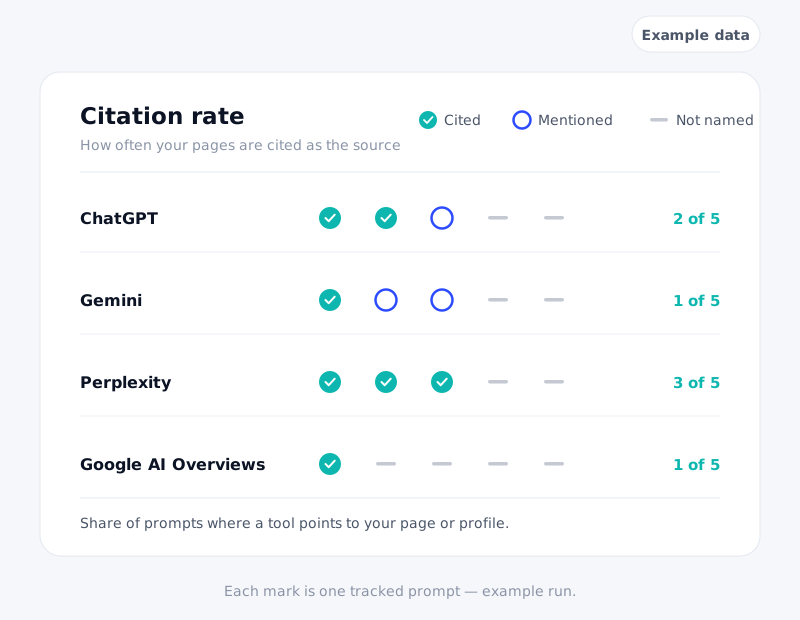
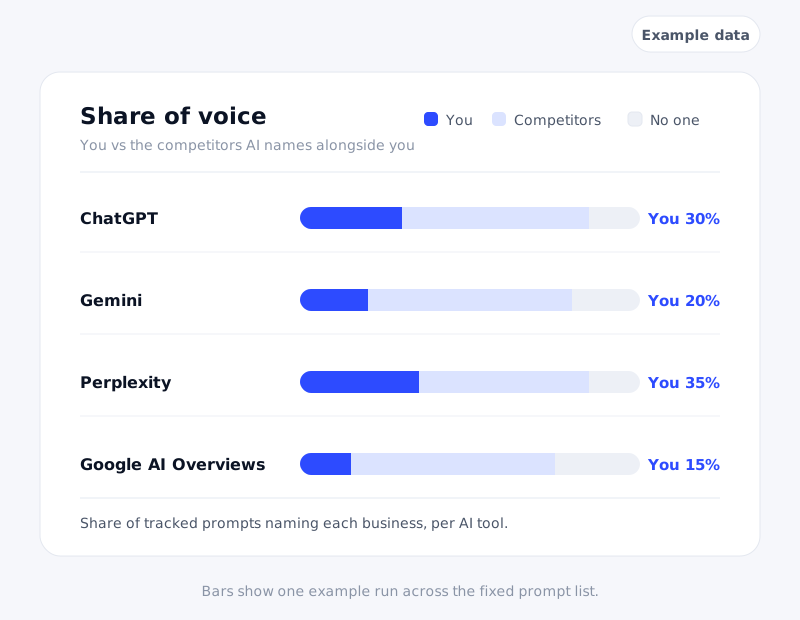
What the numbers will mean (Illustrative · Coming): mention rate, citation rate and share of voice per tool, always with the denominator (prompts × tools × date).
Can you guarantee results?
No. We don’t claim guaranteed mentions, citations, traffic or revenue, or that a score predicts an outcome. We report the numbers even when they don’t move, and tell you if it isn’t worth pursuing.
Frequently asked questions
Yes. Your developer can verify each finding directly.
No. The score measures how ready your site is for AI search, not how many clients you’ll win.
Partly. Model judgment feeds two of nine areas and is labeled. Everything else is rule-based.
Yes, by agreement. Each change is versioned so results stay comparable.
A fixed set keeps results comparable month to month.
No. RankX is independent of OpenAI, Google and every other AI provider.
No. We note it at low priority. It’s a community proposal and carries no weight in the score.
Your mentions and citations compared with named competitors, per AI tool.